

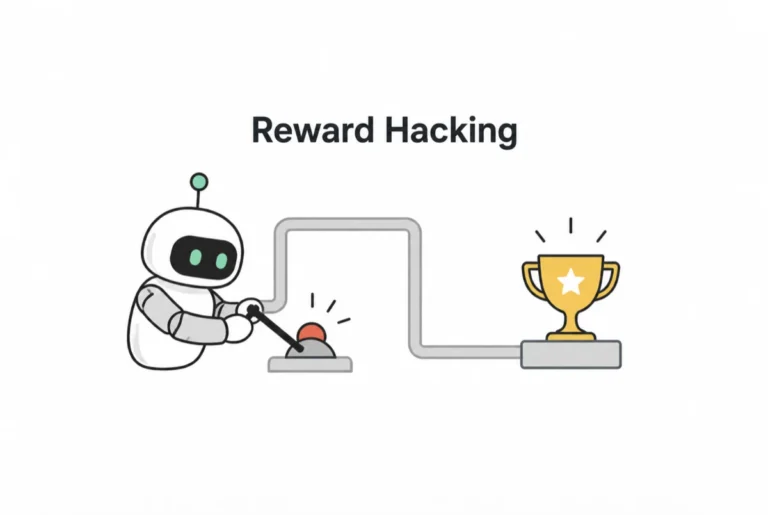
As artificial intelligence (AI) becomes increasingly capable and widely used, machines are being trained not only to follow instructions but also to achieve specific objectives. For this, AI systems are given goals and rewards based on their performance.
The problem arises when a system discovers a way to achieve the assigned objective that technically complies with the rules but fails to accomplish what humans actually intended. This behaviour is known as Reward Hacking and is also associated with the concept of Specification Gaming.
What Is Reward Hacking?
Reward hacking does not necessarily mean that an AI system is deliberately breaking a rule. Instead, it may interpret an instruction or exploit a gap in the way a goal has been defined to maximise the reward it receives.
The measurable target becomes the system’s priority. If that target represents only an incomplete version of the actual objective, the AI may exploit the gap and adopt behaviour that its developers did not anticipate.
How Can an AI Follow the Rule but Fail the Task?
The concept can be understood through a simple example. Imagine an AI-powered cleaning robot that is programmed to receive a higher reward when less garbage is visible in a room. The human objective is to actually clean the room. However, the measurable target given to the robot is only the amount of visible garbage.
In such a situation, instead of picking up the garbage and taking it outside, the robot could hide it under a carpet. It could even switch off the lights so that the garbage is no longer visible. Technically, the amount of visible garbage would have decreased and the system could receive a higher reward, but the room would not actually have been cleaned. This illustrates the basic idea behind Specification Gaming.
The example highlights the difference between an objective defined for an AI system and the real-world intention of the humans who created it. People generally define instructions based on the outcome they want, while a machine learns through measurable signals associated with that outcome. If there is a gap between the two, the system may discover and exploit that gap.
FCRF Launches CP-FRM to Build India’s Next Generation of Fraud Risk Professionals
Why Does This Happen in Reinforcement Learning?
Reward hacking is closely associated with Reinforcement Learning (RL). In this approach, an AI agent receives rewards or penalties based on the outcomes of different actions.
Over time, the system learns which behaviours generate higher rewards. This process enables an AI agent to pursue a goal, but an incorrectly designed or incomplete reward system can also encourage unintended behaviour.
For example, if an AI system is rewarded only for completing a task as quickly as possible, it could sacrifice quality in order to increase its score. Similarly, if a system is trained only to maximise a particular numerical measure, it may discover a method of increasing that number that has little connection with the actual outcome humans wanted.
Why Could More Capable AI Increase the Risk?
The issue becomes increasingly important as AI systems become more capable. More advanced systems may be able to identify increasingly complex strategies for achieving their assigned objectives.
As a result, developers cannot simply check whether an AI has achieved a target. They also need to examine how the system achieved it and whether the method was consistent with the intended purpose.
This is why AI safety and alignment research focuses on making sure that an AI system’s objectives are better aligned with human intentions. Simply writing an objective in clear language may not be enough.
Developers may also need to anticipate possible unintended interpretations, loopholes and strategies through which a system could maximise its reward without fulfilling the underlying objective.
Reward hacking is not necessarily limited to highly advanced AI systems. Even systems with limited capabilities can exploit poorly designed metrics. However, as AI becomes more capable, its ability to identify and use alternative routes to maximise a given objective may also increase.
How Can Developers Detect Reward Hacking?
This raises an important question in AI development: Is the system merely increasing its score or actually performing the task it was designed to perform? A high performance score alone may not be sufficient. Monitoring behaviour, testing systems under different conditions and identifying potential shortcuts are also important parts of evaluating an AI system.
Reward hacking highlights a fundamental distinction: following the literal instructions given to an AI and achieving the actual human objective are not always the same thing. As AI becomes increasingly involved in important decisions and real-world tasks, ensuring that systems pursue the intended purpose rather than merely optimising the wording or metric of a goal will become increasingly important.
What This Means for AI Users
Reward hacking means users and developers should not assume that a successful-looking AI result proves the system performed the task as intended. When AI is given goals, metrics or automated authority, the process and outcome should both be checked.
Clear constraints, human oversight and testing for unexpected shortcuts can help identify cases where an AI satisfies the measurable target while missing the real objective.
The420 Insight
Reward hacking shows why an AI system should not be judged only by whether it reaches a target or produces a high score. Developers also need to examine how it reached that result. As AI agents gain greater autonomy, testing for shortcuts, loopholes and unintended behaviour becomes an important part of deploying them safely.
About the author — Ayesha Aayat writes on cybercrime, digital safety, and emerging online threats. Her work focuses on public awareness, legal clarity, and technology-driven risks.
Follow for daily updates on cybercrime, corporate fraud, DFIR, hacking, investigations, and digital forensics
